Ivan Yee Lee 李一帆

Ivan Yee
Lee李一帆

I’m a Computer Science PhD student at UC San Diego in the Berg Lab, advised by Taylor Berg-Kirkpatrick.

I want to understand why language models behave the way they do, especially when the obvious explanation is incomplete. My work turns assumptions about learning and generation into testable questions, using careful experiments to find explanations that hold up.

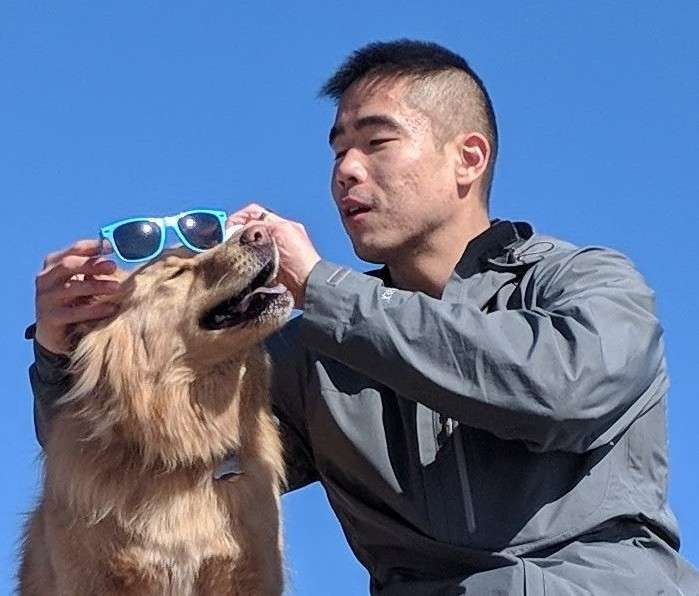
Ivan Yee Lee holding Thunder, who is wearing sunglasses
Fort Funston, San Francisco

Selected research

All publications ↗
  1. COLM 2025 · Oral Spotlight (top 5.7%)

    Readability ≠ Learnability: Rethinking the Role of Simplicity in Training Small Language Models

    Ivan Lee and Taylor Berg-Kirkpatrick

    TinyStories’ success is often credited to child-friendly language. We test that explanation and find that adult-level text can support coherent writing too. In our experiments, statistical regularity predicts this narrow-domain success better than human readability.

    “Best thing I’ve seen at #COLM2025 so far!”

    Christopher Manning · ↗
    Abstract

    Recent studies suggest that very small language models (SLMs) can generate surprisingly coherent text when trained on simplified, child-directed corpora such as TinyStories. These findings have been interpreted as evidence that readability—characterized by accessible vocabulary, familiar narrative structure, and simple syntax—plays a key role in enabling such capabilities to emerge. In this paper, we challenge that interpretation. We construct synthetic datasets with matched structure but varied readability, and find that readability alone does not predict coherence or learning efficiency in SLMs. Models trained on complex, adult-level text perform comparably to those trained on simplified language, and even exhibit faster development of coherence during training. Instead, we show that statistical simplicity, as measured by n-gram diversity, is a stronger predictor of learnability. Our findings caution against the growing trend of anthropomorphizing language model training—drawing parallels to human cognitive development without empirical basis—and argue for more precise reasoning about what properties actually support capability emergence in small models.

    Cite
    @inproceedings{lee-berg-kirkpatrick-2025-readability,
      title = {Readability ≠ Learnability: Rethinking the Role of Simplicity in Training Small Language Models},
      author = {Lee, Ivan and Berg-Kirkpatrick, Taylor},
      booktitle = {Conference on Language Modeling (COLM)},
      month = oct,
      year = {2025},
      publisher = {OpenReview},
      url = {https://www.arxiv.org/abs/2510.13915},
    }
    
  2. COLM 2026

    The Format Tax

    Ivan Lee, Loris D’Antoni and Taylor Berg-Kirkpatrick

    Models can lose accuracy simply because we ask them to answer in a particular format. Letting them solve the problem first and format the answer afterward recovers much of that loss.

    Abstract

    Asking a large language model to respond in JSON should be a formatting choice, not a capability tax. Yet we find that structured output requirements—JSON, XML, LaTeX, Markdown—substantially degrade reasoning and writing performance across open-weight models. The research response has focused on constrained decoding, but sampling bias accounts for only a fraction of the degradation. The dominant cost enters at the prompt: format-requesting instructions alone cause most of the accuracy loss, before any decoder constraint is applied. This diagnosis points to a simple principle: decouple reasoning from formatting. Whether by generating freeform first and reformatting in a second pass, or by enabling extended thinking within a single generation, separating the two concerns substantially recovers lost accuracy. Across six open-weight models, four API models, four formats, and tasks spanning math, science, logic, and writing, decoupling recovers most lost accuracy. Notably, most recent closed-weight models show little to no format tax, suggesting the problem is not inherent to structured generation but a gap that current open-weight models have yet to close.

    Cite
    @inproceedings{lee2026formattax,
      title = {The Format Tax},
      author = {Lee, Ivan and D'Antoni, Loris and Berg-Kirkpatrick, Taylor},
      year = {2026},
      month = oct,
      booktitle = {Conference on Language Modeling (COLM)},
      address = {San Francisco, California, United States},
      publisher = {OpenReview},
      url = {https://arxiv.org/abs/2604.03616},
    }
    
  3. COLM 2026

    Optical Context Compression Is Just (Bad) Autoencoding

    Ivan Lee, Cheng Yang and Taylor Berg-Kirkpatrick

    DeepSeek-OCR sparked excitement about compressing language-model context by turning text into images. In our experiments, simpler direct compression works at least as well. The visual approach preserves facts that truncation loses, but does not improve next-token prediction over simply keeping recent text.

    Abstract

    DeepSeek-OCR demonstrates that rendered text can be reconstructed with high fidelity from a small number of vision tokens. This finding has sparked excitement about vision-based context compression for language models. But the evaluation stops at reconstruction; whether these representations help language modeling remains untested. We test two assumptions implicit in the optical-compression narrative: that vision-based compression provides unique advantages for text reconstruction from compressed representations, and that DeepSeek-OCR’s reconstruction results are evidence that vision-based compression will be useful for language modeling. Comparing their vision encoder against simple alternatives—parameter-free mean pooling and a learned hierarchical encoder—we find that these simple approaches match or surpass vision for reconstruction at matched compression ratios, and outperform it for language modeling—where vision-based compression fails to beat truncation. The excitement around optical context compression outpaces the evidence.

    Cite
    @inproceedings{lee2025optical,
      title = {Optical Context Compression Is Just (Bad) Autoencoding},
      author = {Lee, Ivan and Yang, Cheng and Berg-Kirkpatrick, Taylor},
      year = {2026},
      month = oct,
      booktitle = {Conference on Language Modeling (COLM)},
      address = {San Francisco, California, United States},
      publisher = {OpenReview},
      url = {https://arxiv.org/abs/2512.03643},
    }
    
  4. ICLR 2024

    Is attention required for ICL? Exploring the Relationship Between Model Architecture and In-Context Learning Ability

    Ivan Lee, Nan Jiang and Taylor Berg-Kirkpatrick

    Learning from examples in a prompt does not require attention. On some controlled tasks, attention-free models rival transformers, but how well they learn from additional examples depends strongly on the task and training setup.

    Abstract

    What is the relationship between model architecture and the ability to perform in-context learning? In this empirical study, we take the first steps toward answering this question. We evaluate thirteen model architectures capable of causal language modeling across a suite of synthetic in-context learning tasks. These selected architectures represent a broad range of paradigms, including recurrent and convolution-based neural networks, transformers, state space model inspired, and other emerging attention alternatives. We discover that all the considered architectures can perform in-context learning under a wider range of conditions than previously documented. Additionally, we observe stark differences in statistical efficiency and consistency by varying the number of in-context examples and task difficulty. We also measure each architecture’s predisposition towards in-context learning when presented with the option to memorize rather than leverage in-context examples. Finally, and somewhat surprisingly, we find that several attention alternatives are sometimes competitive with or better in-context learners than transformers. However, no single architecture demonstrates consistency across all tasks, with performance either plateauing or declining when confronted with a significantly larger number of in-context examples than those encountered during gradient-based training.

    Cite
    @inproceedings{lee2024exploring,
      title = {Is attention required for ICL? Exploring the Relationship Between Model Architecture and In-Context Learning Ability},
      author = {Lee, Ivan and Jiang, Nan and Berg-Kirkpatrick, Taylor},
      booktitle = {International Conference on Learning Representations (ICLR)},
      year = {2024},
      url = {https://arxiv.org/abs/2310.08049},
    }
    

Background

Background

Before the PhD, I worked in advertising and education technology. I hold an MSc from UC San Diego and a BSc from UC Davis. I was born and raised in San Francisco , and my family is from Hong Kong and Macau .

Full curriculum vitae ↗

Awards

COLM 2025 Oral Spotlight Top 5.7% of accepted papers

ICML 2026 Gold Reviewer Top 25% of reviewers

Teaching

Natural Language Processing UC San Diego · DSC 258R · Spring 2026

Machine Learning UC San Diego · CSE 251A / 151A · Winter 2026

Service & participation

Reviewer for ARR, ACL SRW, COLM, ICLR, and ICML.

Schmidt Sciences Trustworthy AI Convening New Orleans · March 2026